November 5, 2026
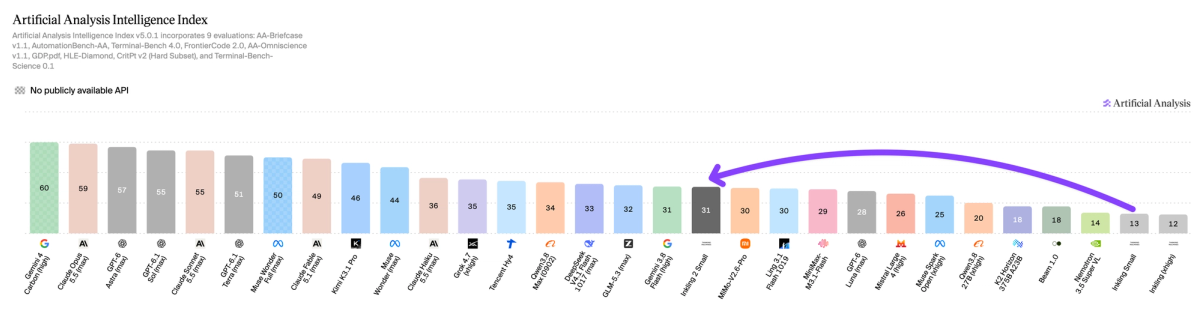
Thinking Machines has released Inkling 2 Small, scoring 31 on the Artificial Analysis Intelligence Index - their plan to release its weights would make it the highest-scoring open weights model developed outside China based on current rankings
See model pageInkling 2 Small is launching as a proprietary model, available first-party through Thinking Machines' Tinker platform and Tinker Playground, with weights to be released at a later date. Its score is up 18 points from Inkling Small, with ~4x as many output tokens per task. It matches Google DeepMind's Gemini 3.8 Flash (high) and surpasses Xiaomi's MiMo-V2.6-Pro on the Artificial Analysis Intelligence Index v5.0.1.
Key takeaways:
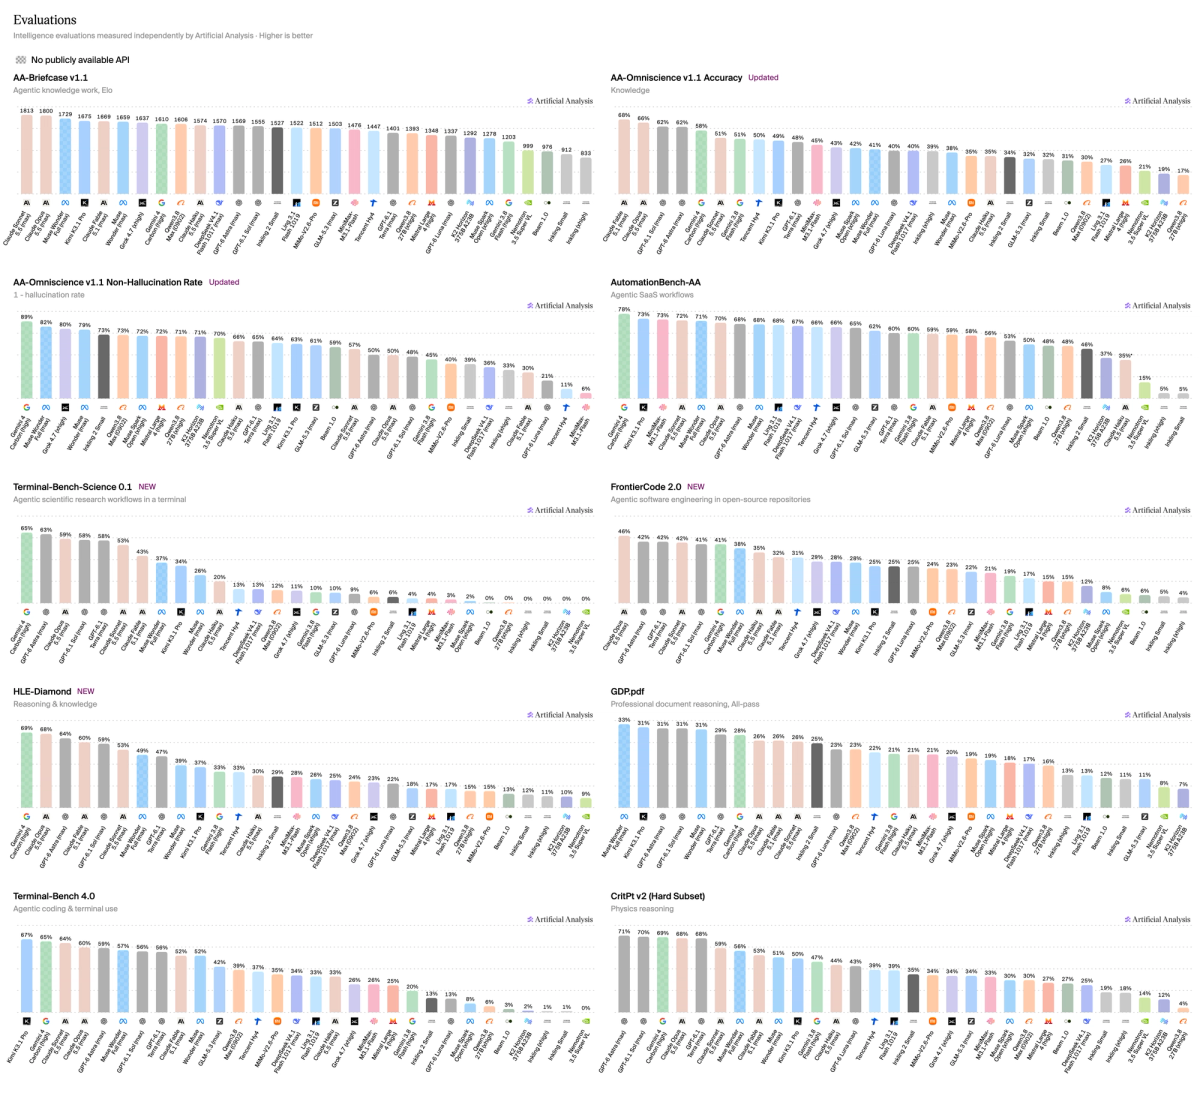
➤ Large gains over Inkling Small, especially on agentic tasks: AutomationBench-AA rises from 5% to 46% and FrontierCode 2.0 from 5% to 25%. HLE-Diamond also rises from 12% to 29%.
➤ Different coding strengths from Claude Sonnet 5.5 (medium): Inkling 2 Small scores 25% on FrontierCode 2.0 vs. 11% for Claude Sonnet 5.5 (medium), but 13% on Terminal-Bench 4.0 vs. 30%.
➤ Creative agentic scores above Claude Haiku 5.5 and Grok 4.7 on AA-3D: Inkling 2 Small also scores above Gemini 3.8 Flash on both AA-3D and Code2Video-AA, but behind Claude Sonnet 5.5 on both.
➤ Research-level physics improves, but trails Gemini 3.8 Flash (high): Inkling 2 Small scores 56% on CritPt v2, up from 34% for Inkling Small, vs. 65% for Gemini 3.8 Flash (high).
➤ Fewer hallucinations from more selective answering: On AA-Omniscience v1.1, the hallucination rate falls from Inkling Small's 61% to 27%, while accuracy rises from 32% to 34% and the attempt rate falls from 77% to 53%.
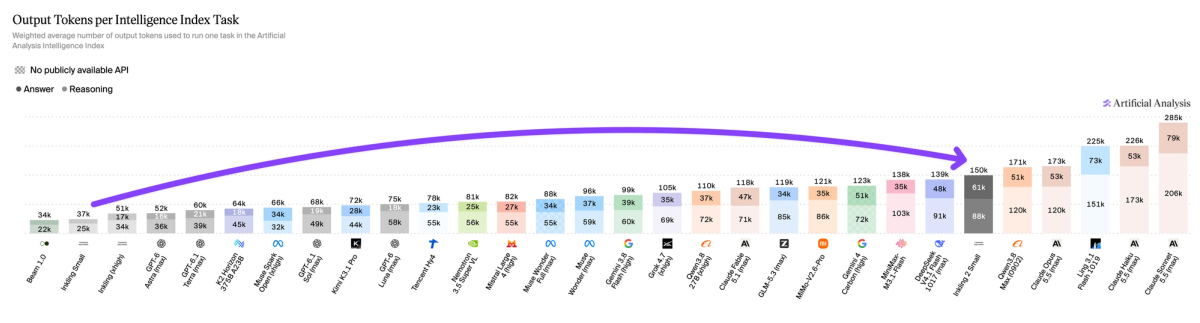
➤ ~4x as many output tokens: Inkling 2 Small averages ~150K output tokens per Intelligence Index task vs. ~37K for Inkling Small, ~31K for Claude Sonnet 5.5 (medium), and ~99K for Gemini 3.8 Flash (high).
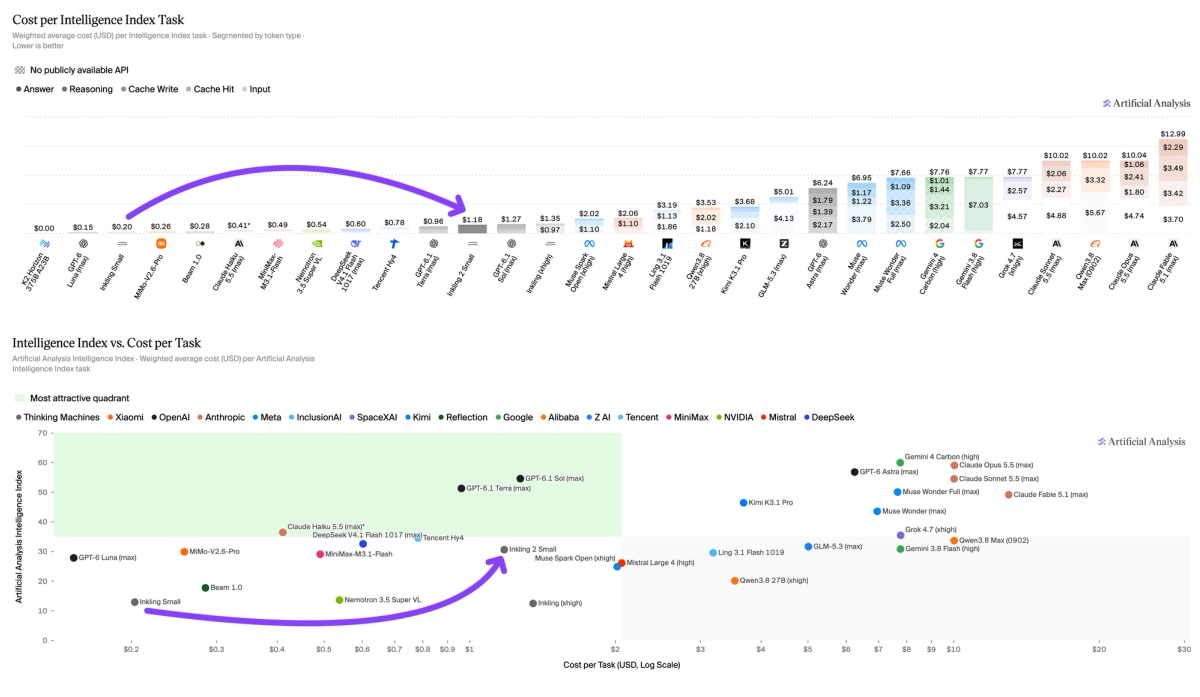
➤ Almost 6x the cost of Inkling Small, but cheaper than several other models with similar Intelligence Index scores: Inkling 2 Small costs $1.18 per Intelligence Index task vs. $0.20 for Inkling Small, $7.77 for Gemini 3.8 Flash (high), and $10.02 for Claude Sonnet 5.5 (medium).
Key model details:
➤ Type: Proprietary reasoning model at launch; Apache 2.0 weights release planned (date unconfirmed)
➤ Modalities: Text and image input, text output
➤ Size: 594B total parameters / 17B active parameters
➤ Pricing: $0.30/$1.00 per 1M input/output tokens ($0.03 per 1M cached input tokens)
➤ Availability at launch: Tinker and Tinker Playground
Congratulations to the team at Thinking Machines on the release!
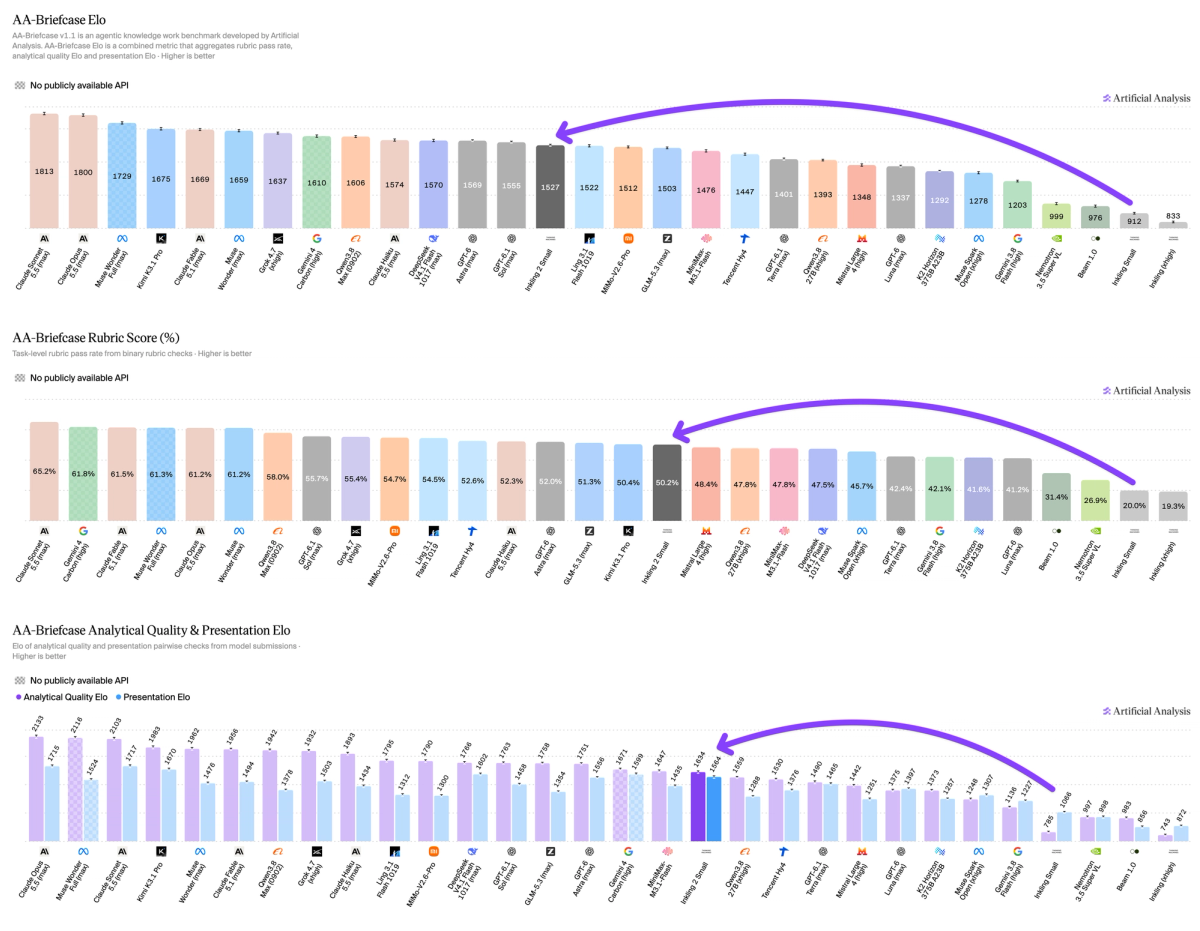
Inkling 2 Small scores 615 Elo points higher than Inkling Small on AA-Briefcase, with 2.5x the rubric pass rate.
AA-Briefcase tests long-horizon business workflows requiring spreadsheets, presentations, and memos. Inkling 2 Small scores 1527 Elo vs. 912 Elo for Inkling Small, 1439 Elo for Claude Sonnet 5.5 (medium), and 1203 Elo for Gemini 3.8 Flash (high).
It passes 50% of rubric checks vs. 20% for Inkling Small, with analytical quality at 1634 Elo and presentation at 1564 Elo.
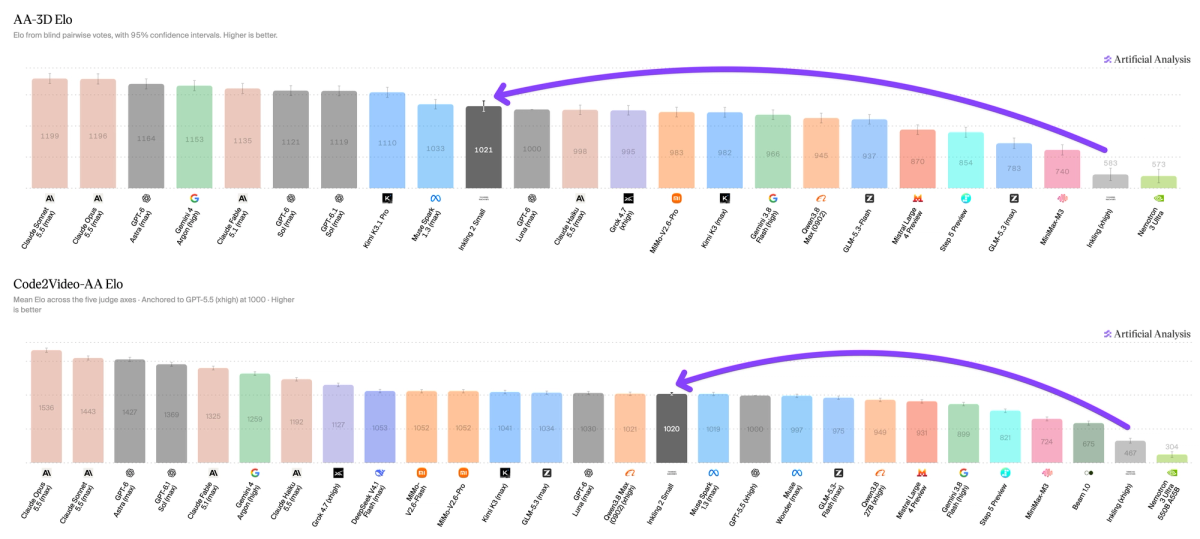
Inkling 2 Small makes large gains over Inkling (xhigh) on AA-3D and Code2Video-AA, with scores close to Muse Spark 1.3 and Qwen3.8 Max, respectively.
AA-3D tests models’ ability to create interactive 3D experiences. Inkling 2 Small scores 1021 Elo vs. 966 Elo for Google DeepMind's Gemini 3.8 Flash and 1033 Elo for Meta's Muse Spark 1.3 (max).
On Code2Video-AA, which tests models’ ability to create videos using code, Inkling 2 Small scores 1020 Elo vs. 899 Elo for Gemini 3.8 Flash and 1021 Elo for Alibaba's Qwen3.8 Max (0902) (xhigh).
Compared with Inkling (xhigh), it gains 438 Elo on AA-3D (1021 vs. 583) and 553 Elo on Code2Video-AA (1020 vs. 467).
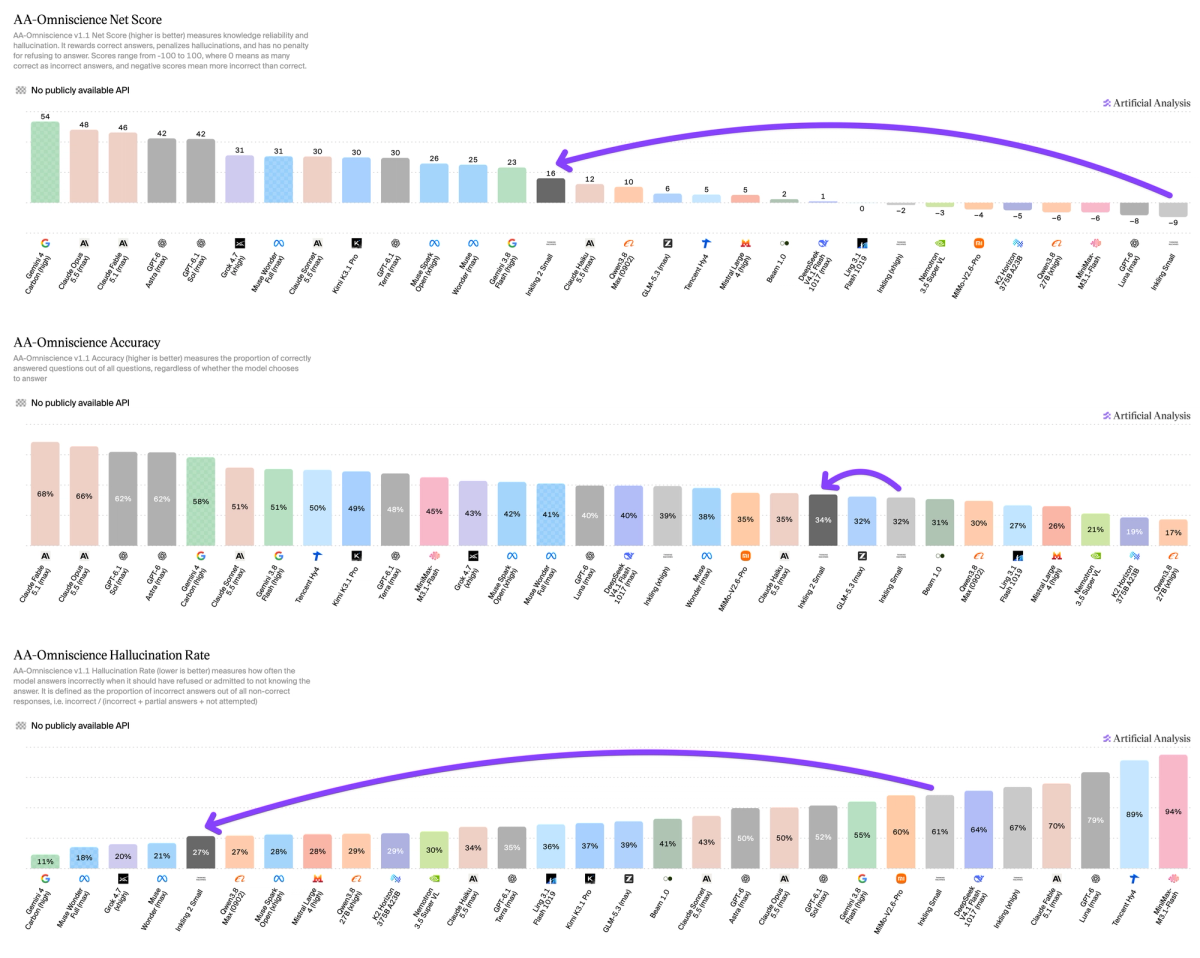
Inkling 2 Small hallucinates less mainly because it answers fewer questions, while accuracy improves only slightly.
On AA-Omniscience v1.1 its net score improves to 16 from -9 for Inkling Small, but remains behind Gemini 3.8 Flash (high, 23) and Claude Sonnet 5.5 (medium, 19). Its hallucination rate falls to 27% from Inkling Small’s 61%, while its attempt rate falls to 53% from 77% and accuracy rises to 34% from 32%.
Inkling 2 Small averages ~150K output tokens per Intelligence Index task, ~4x that of Inkling Small’s ~37K.
It also uses more output tokens than Gemini 3.8 Flash (high, ~99K) and Claude Sonnet 5.5 (medium, ~31K).
Inkling 2 Small costs $1.18 per Task in the Intelligence Index, up almost 6x from Inkling Small.
Token prices for Inkling 2 Small are $0.30/$1.00/$0.03 per 1M input/output/cache hit tokens.
Full results across the evaluations in the Artificial Analysis Intelligence Index v5.0.1
Read the latest
Multimodal Knowledge Agent (MKA) benchmark: testing knowledge work capabilities with complex visual files
We’ve partnered with Google DeepMind to launch their Multimodal Knowledge Agent (MKA) evaluation, a new benchmark for agentic knowledge work over complex visual files
November 10, 2026
Endpoint Accuracy Index v1.1: Tighter long context intervals and expanded model coverage
We are launching the Artificial Analysis Endpoint Accuracy Index v1.1, a minor version upgrade alongside new coverage for GLM-5.3 Flash and Muse Spark Open.
November 9, 2026
Meta's Muse Ember is the cheapest model scoring 36 on the Intelligence Index
Meta's newest model Muse Ember scores 36 on the Artificial Analysis Intelligence Index, matching Claude Haiku 5.5 (max) at a third of the Cost per Task
November 9, 2026