May 20, 2026
Cohere launches open weights model Command A+ that achieves 37 on the Artificial Analysis Intelligence Index
See model pageThe release of Command A+ places Cohere in line with Claude 4.5 Haiku on the Intelligence Index, and just above NVIDIA Nemotron 3 Super and Gemini 3.1 Flash-Lite.
Key Takeaways:
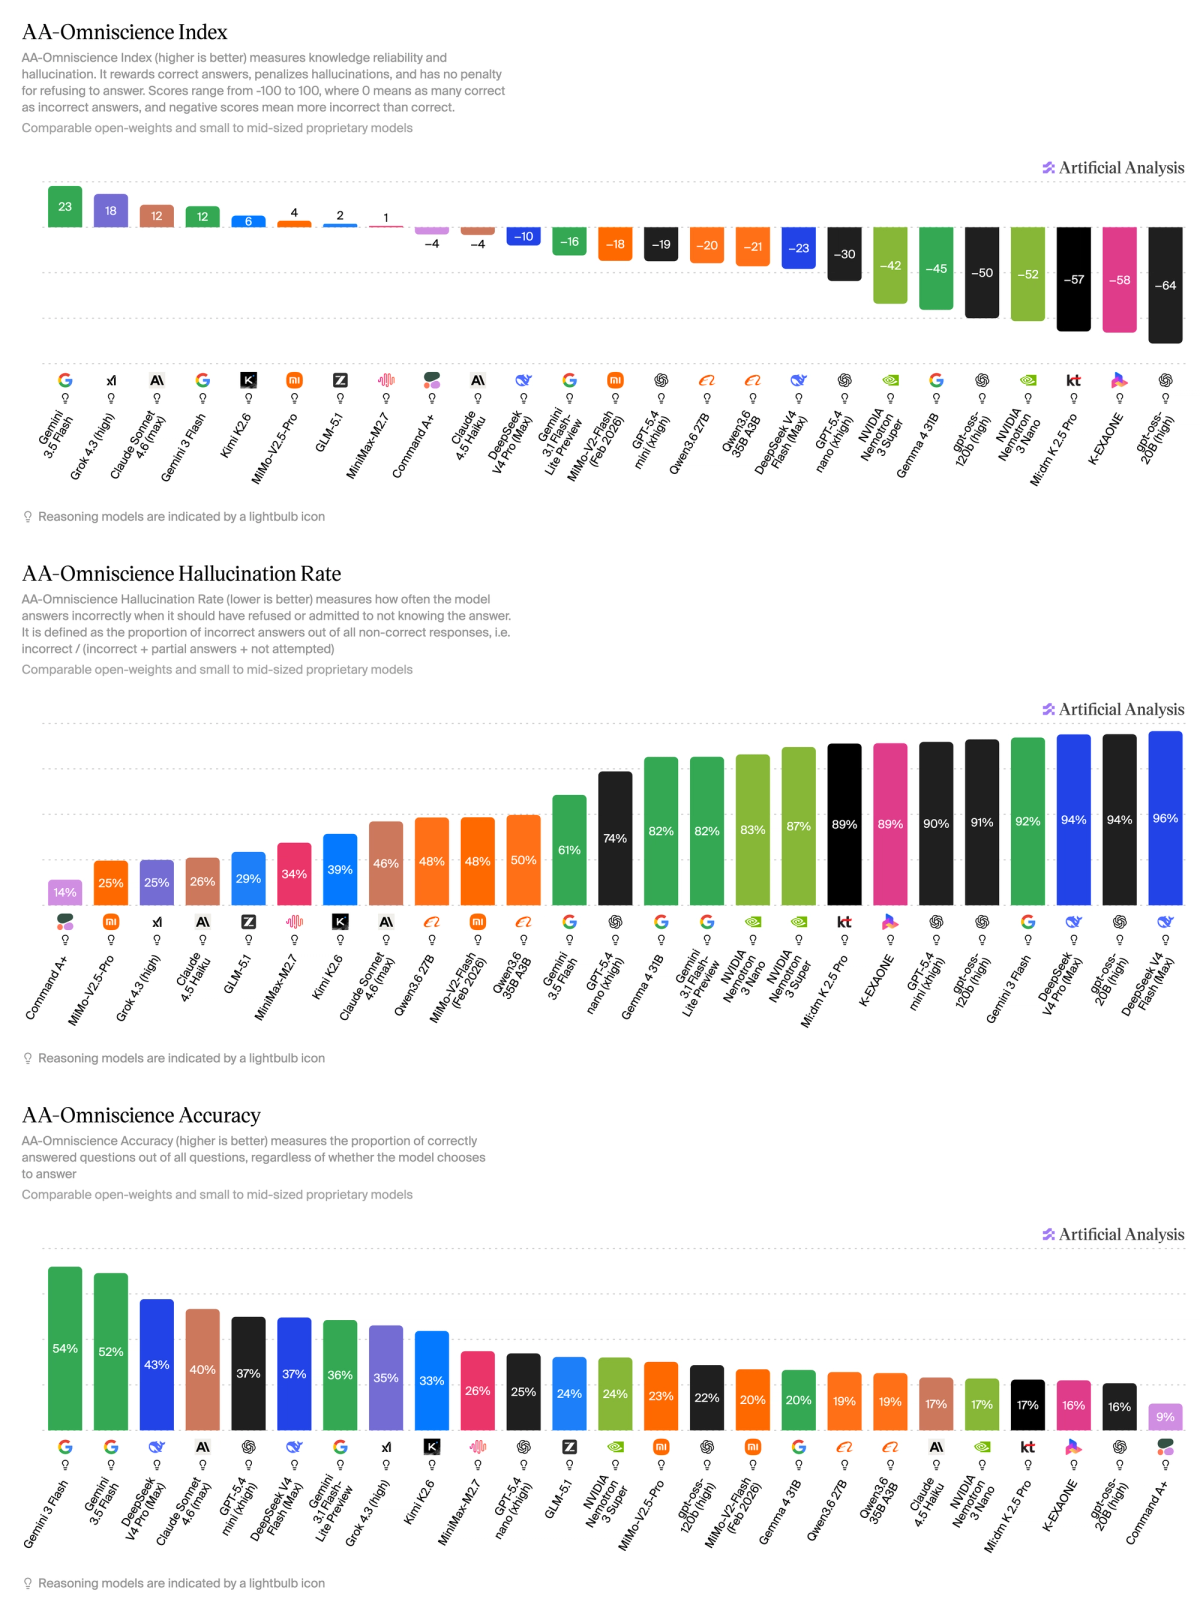
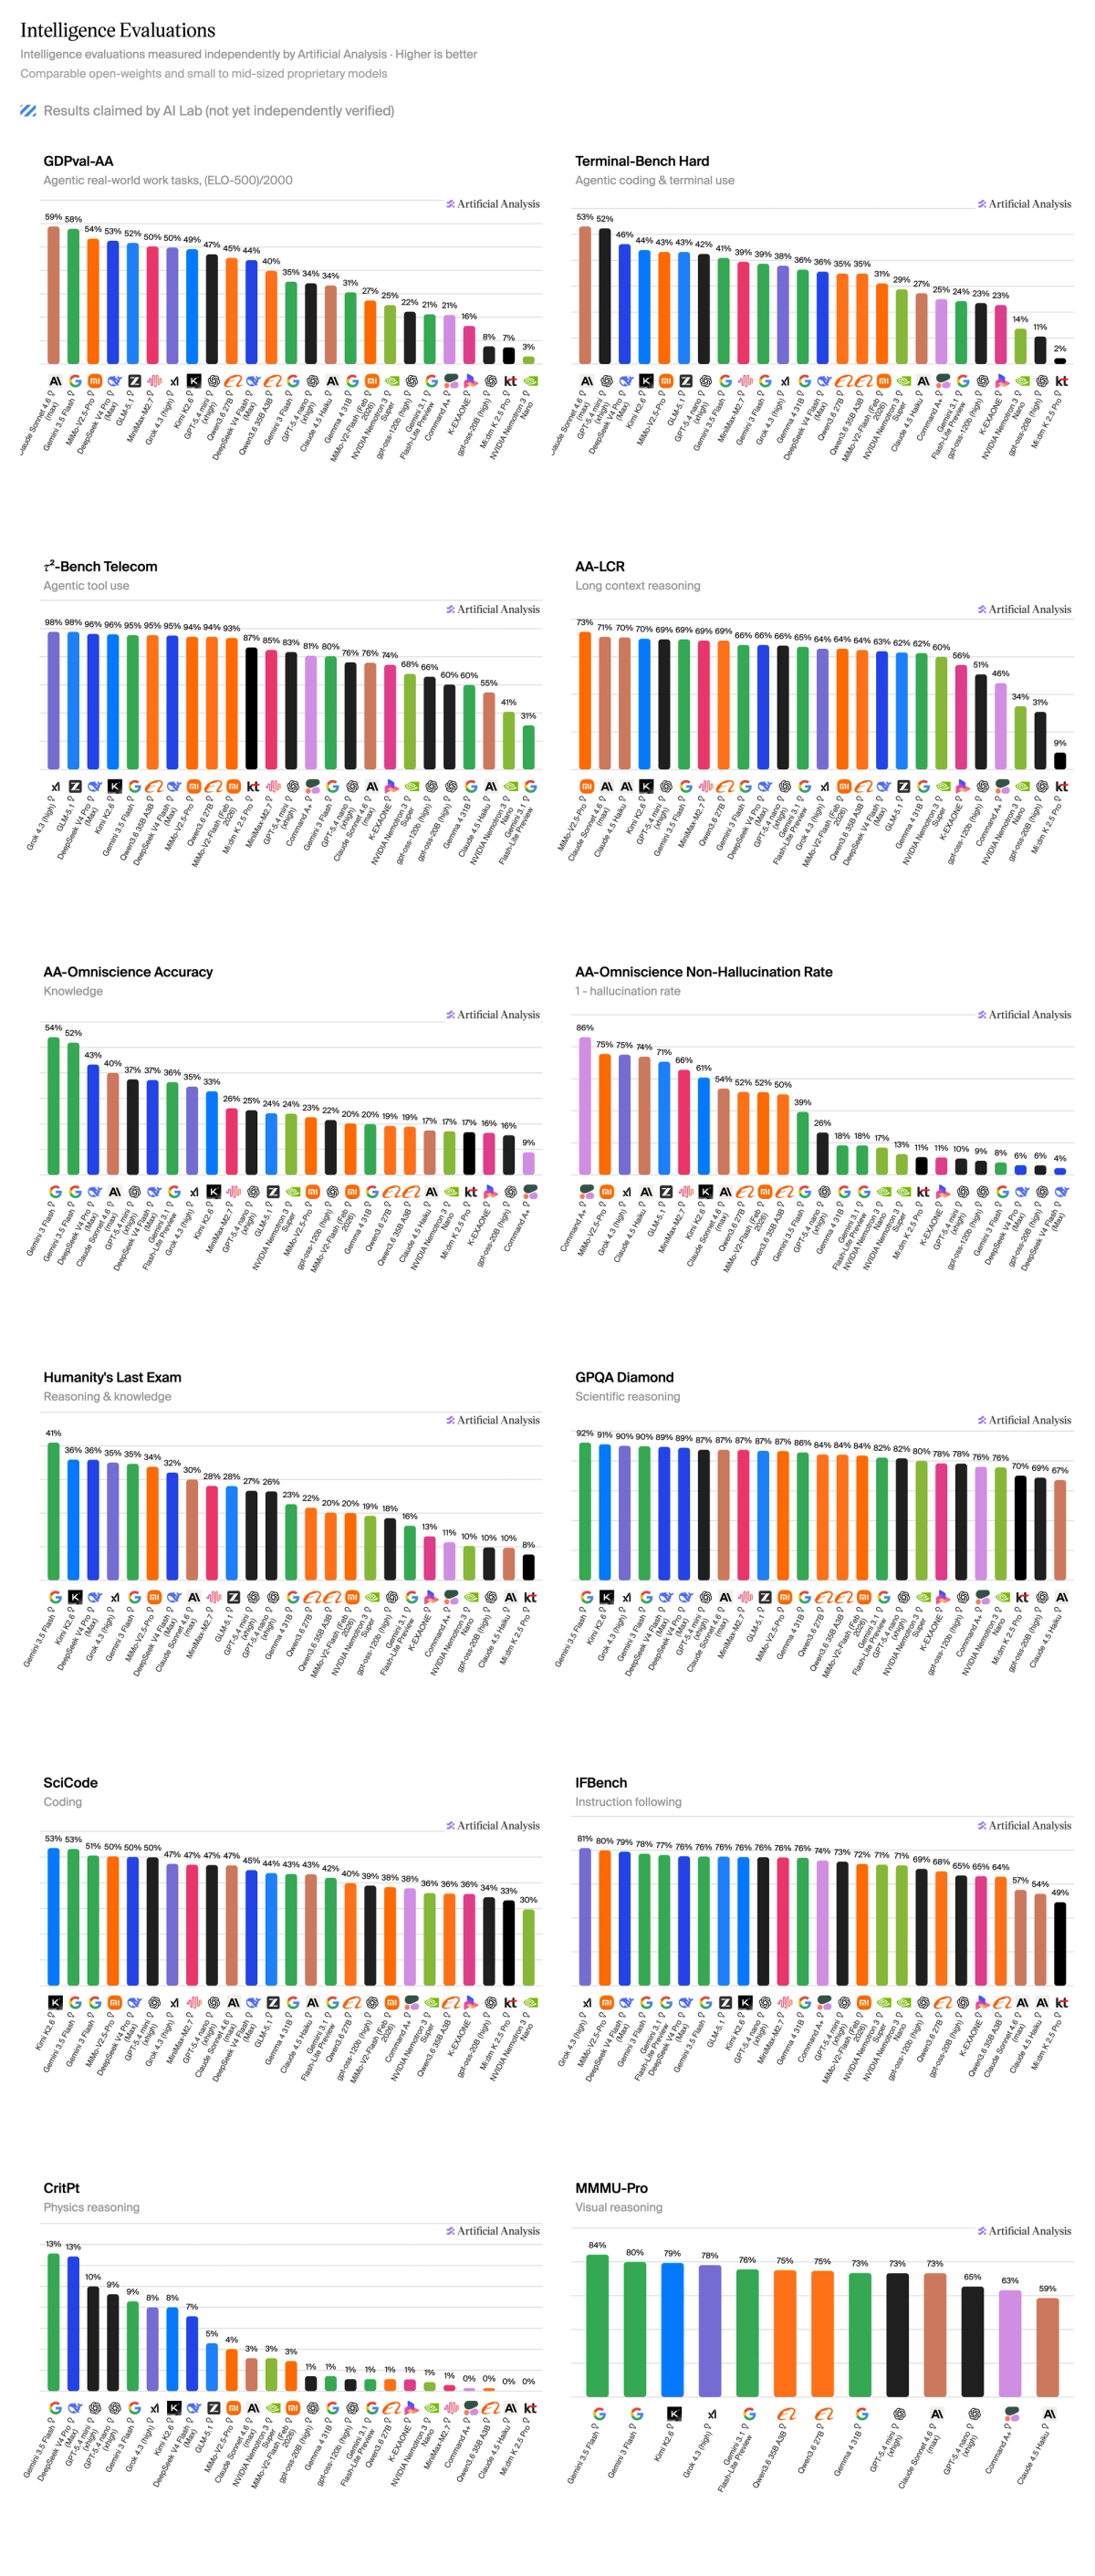
➤ Command A+ ranks first on AA-Omniscience Non-Hallucination at 86%, ~3 percentage points ahead of the next-best model. Its AA-Omniscience Accuracy is 9%, so the headline AA-Omniscience score lands at -4, demonstrating a similar archetype to Claude 4.5 Haiku, where the model knows its limits
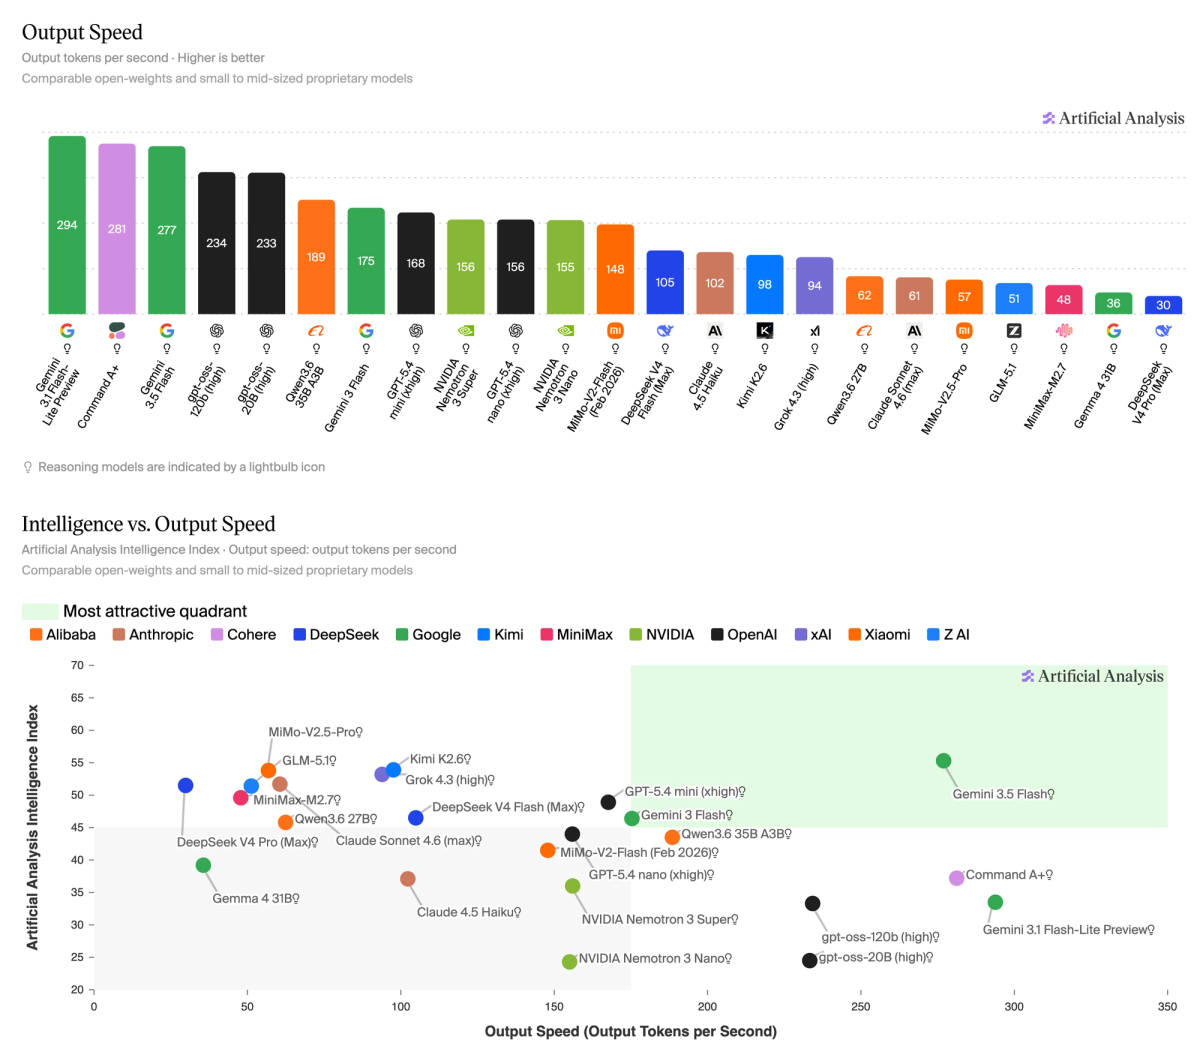
➤ On Cohere’s API, Command A+ (~281 output tokens per second) is faster than several comparable open-weights and small to mid-sized proprietary models (e.g., GPT-5.4 nano, Claude 4.5 Haiku, and Grok 4.3), but still slower than Gemini 3.1 Flash-Lite Preview, which outputs 304 tokens per second
➤ Command A+ trails its peer set on scientific reasoning (HLE ~11%, GPQA Diamond ~76%) and on coding (Terminal-Bench Hard ~25%, SciCode ~38%), consistent with gaps on the hardest science and agentic coding benchmarks
➤ It supports visual reasoning and scores 63% on MMMU-Pro (between Claude 4.5 Haiku at 59% and GPT-5.4 nano (xhigh) at 65%)
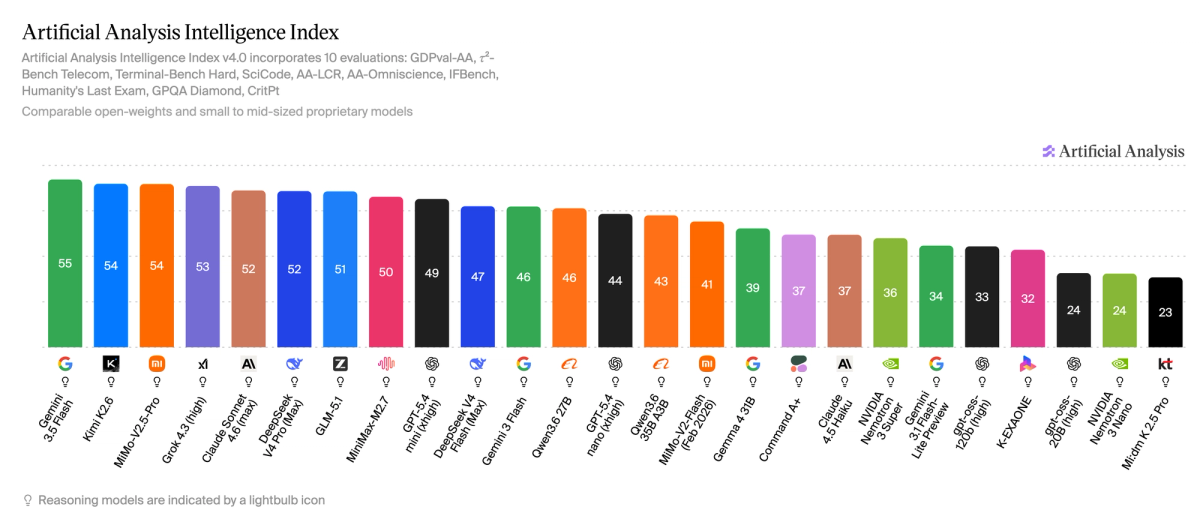
In our pre-release testing, Command A+ performed strongly on speed for its intelligence, reaching 281 output tokens per second. This reflects higher intelligence and speed than models such as gpt-oss-120b, but sits behind the new Pareto frontier established by Gemini 3.5 Flash
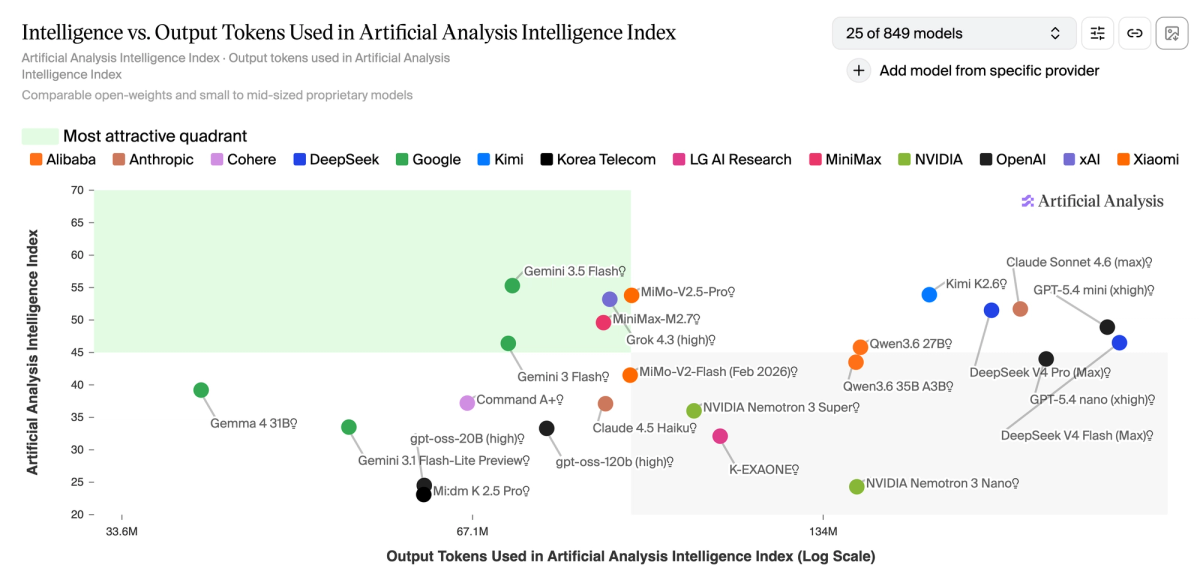
Amongst comparable models, Command A+ is competitive on intelligence vs. output tokens to run the Artificial Analysis Intelligence Index
On AA-Omniscience, our knowledge and hallucination evaluation, Command A+ fits a positive archetype where it knows its limitations: although it has relative low performance on AA-Omniscience Accuracy, it also hallucinates the least on AA-Omniscience, resulting in a fairly strong relative headline AA-Omniscience score of -4
Breakdown of individual evaluations:
See Artificial Analysis for further details and benchmarks: https://artificialanalysis.ai/models/command-a-plus
Read the latest
Gemini 4 Carbon is the new #1 on the Artificial Analysis Intelligence Index v5
Google’s Gemini 4 Carbon is the new #1 on the Artificial Analysis Intelligence Index v5, and second only to Claude Opus 5.5 on the Artificial Analysis Coding Agent Index
October 28, 2026
GitHub Copilot Fusion orchestrates Anthropic and OpenAI models to balance performance and cost
itHub has released Copilot Fusion in GitHub Copilot, which orchestrates between Anthropic and OpenAI models. It scores 2 points below Opus 5.5 in Claude Code at half the Cost per Task in the Coding Agent Index
October 28, 2026
Announcing Artificial Analysis Intelligence Index v5
Index v5 features 2 new benchmarks and 3 upgrades. For the first time, the majority of the Index is built on private datasets
October 27, 2026